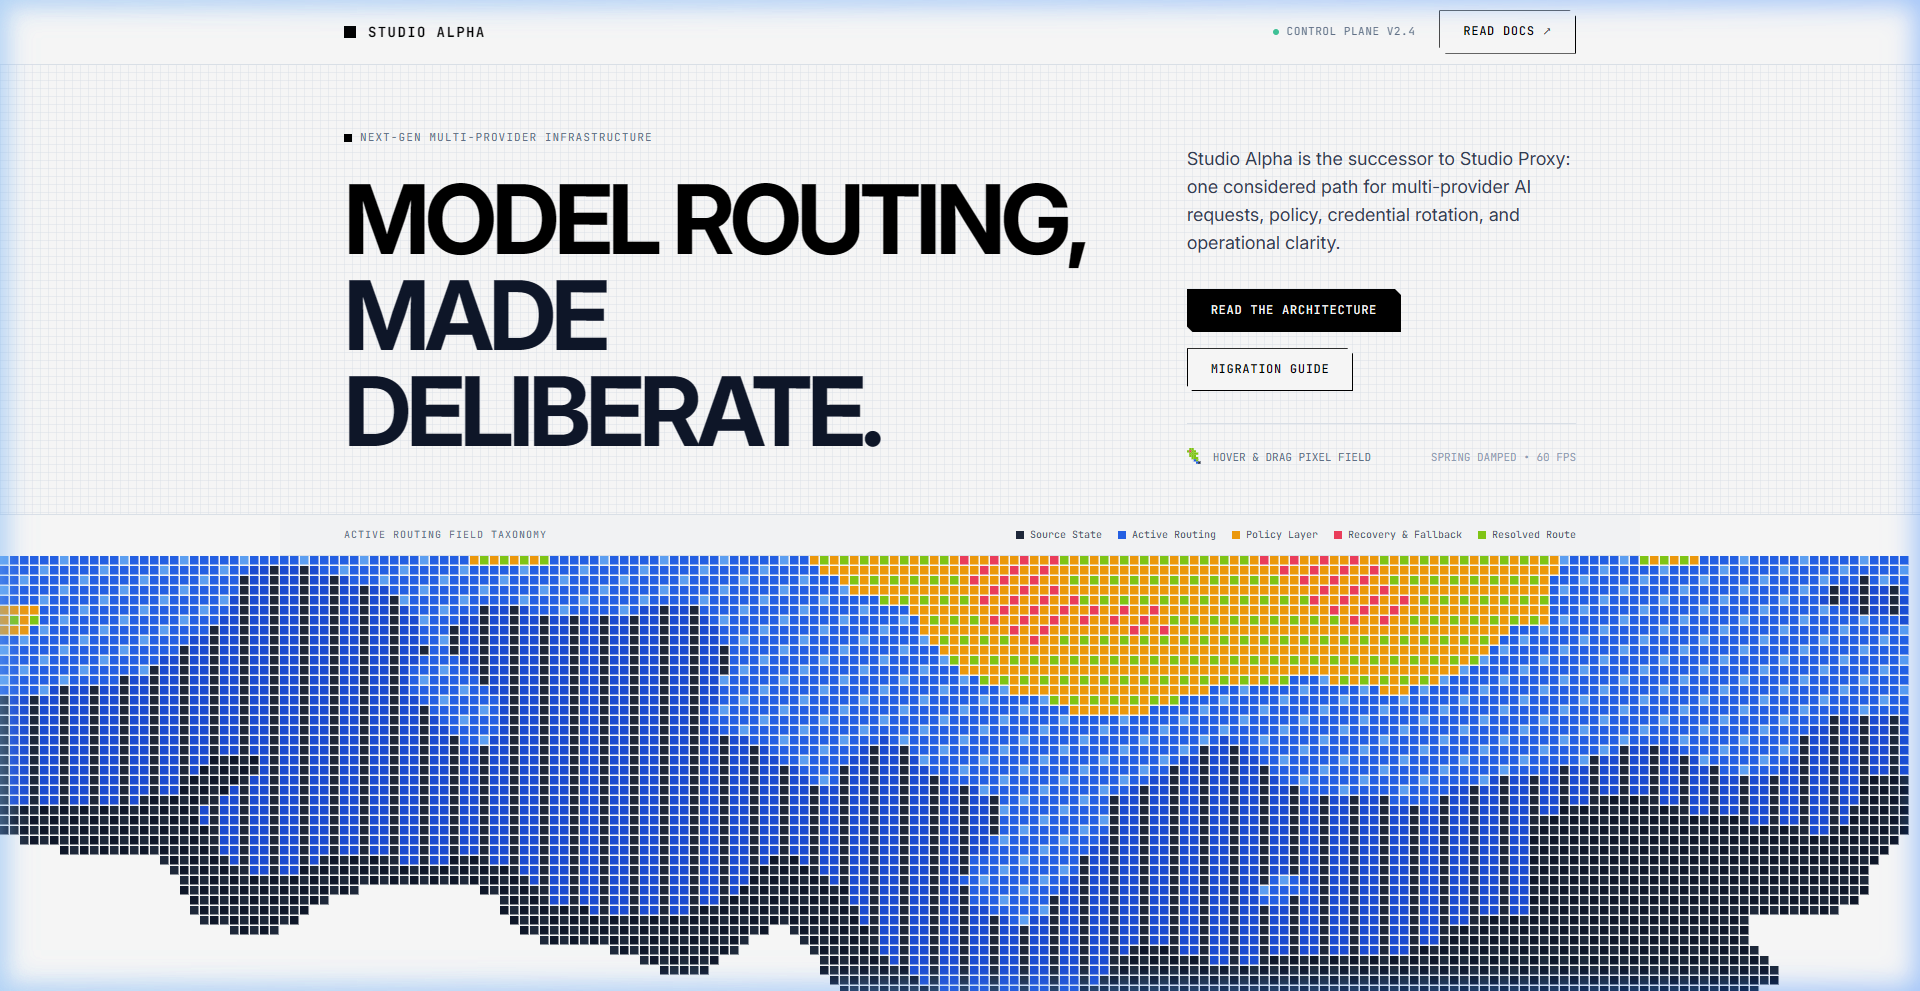
How RunThrou built resilient multi-provider AI routing middleware for Studio Alpha with sub-100ms health-checking and automatic failover across model providers.
Generative AI applications that depend on a single foundation-model provider routinely hit upstream rate limits and unplanned downtime, surfacing as severe user-facing latency and lost revenue. Studio Alpha needed production-grade infrastructure that could absorb those shocks without ever showing them to end users.
The team also lacked observability: when something went wrong, they could not see which provider, which route, or which request was the cause — making incident response slow and root-cause analysis guesswork.
RunThrou designed and shipped a smart routing matrix with sub-100ms health-checking and dynamic multi-provider rotation across Anthropic Claude, OpenAI GPT-4o, and DeepSeek. The frontend is a pixel-grid observability dashboard that surfaces per-request telemetry, model health, and failover events in real time.
Under the hood: a frontend architecture for the control plane, a real-time WebGL telemetry layer, API load-balancing controls, credential rotation UI, and a fallback rules engine that operators can adjust without redeploys.
The result is a control plane that engineering teams actually use — live, interactive, and fast enough to debug production traffic in seconds.
Studio Alpha now runs mission-critical AI workloads on a routing layer that bends under load instead of breaking. The platform has scaled to multiple product lines and geographies, with the same control plane reused across deployments.
Engineering teams that previously had to wait for incident reports now see provider health in real time and shift traffic before users notice — turning AI reliability from a fire drill into a background process.
If you need high-availability AI infrastructure, multi-provider routing, or a full reliability rebuild, we should talk.
Start a conversation →